
Efficient Data Handling in Python: Using Generators for Large Datasets
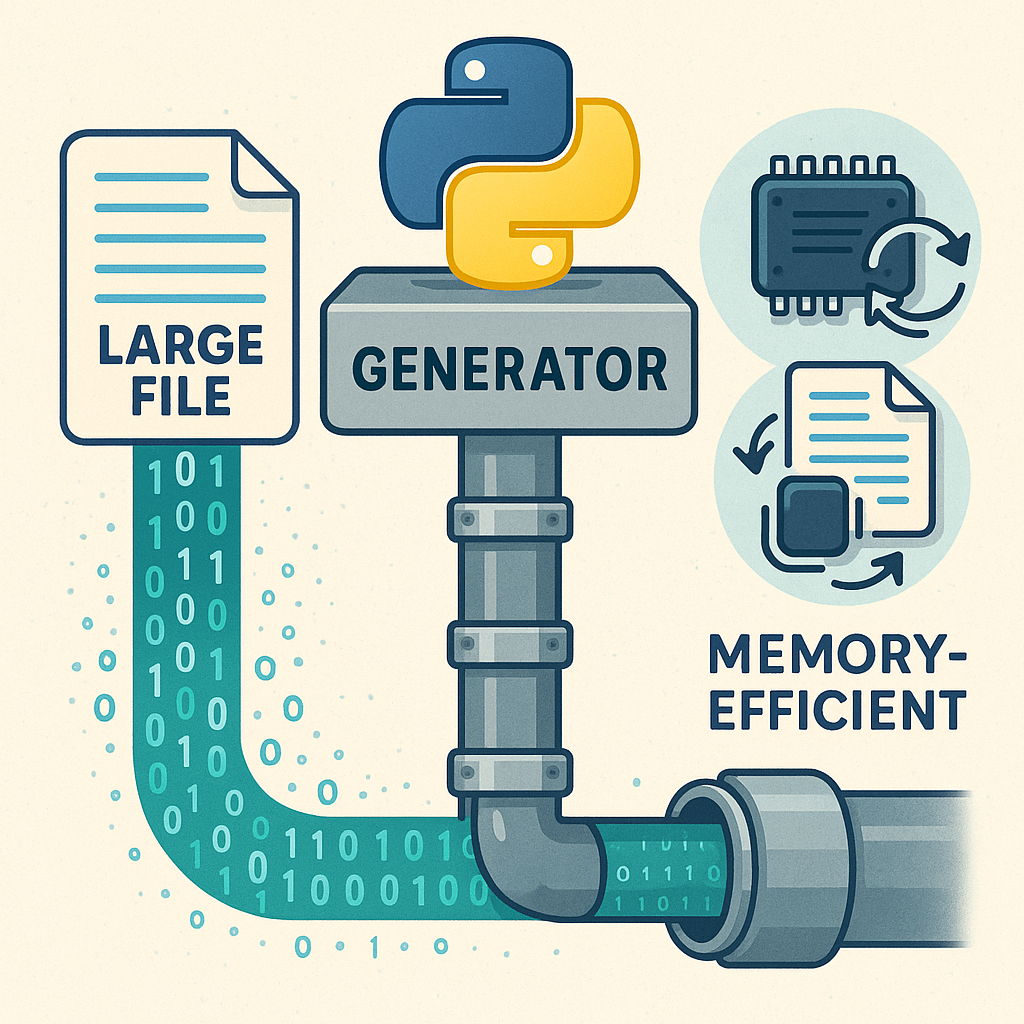
In the fast-paced world of data science and software development, handling large datasets efficiently is crucial. One of Python’s most powerful features for this purpose is generators. By leveraging generators, developers can process large amounts of data without exhausting system memory, enabling smoother and faster computations. This blog post delves into how generators can be used in Python to handle large datasets effectively, complete with illustrative code examples and practical tips.
1. Understanding Python Generators
Generators are a special class of iterators in Python, designed to traverse over a collection of items one at a time. Unlike lists, generators do not store their contents in memory, making them highly efficient for handling large datasets. A generator can generate items on-the-fly as they are requested during iteration.
Here’s a simple example to illustrate a generator function:
def count_up_to(max_value):
    n = 1
    while n <= max_value:
        yield n
        n += 1

counter = count_up_to(5)
for number in counter:
    print(number)
In this example, the count_up_to function is a generator that yields numbers from 1 to 5, one at a time, as requested by the iteration loop.
2. Processing Large Files Line-By-Line
One of the practical use cases of generators is to process large files line-by-line, minimizing memory usage. Consider a scenario where you need to analyze a large log file. Using generators, you can read and process each line individually.
Here's an example of reading a file using a generator:
def read_large_file(file_path):
    with open(file_path, 'r') as file:
        for line in file:
            yield line.strip()

for line in read_large_file('large_log.txt'):
    process(line)  # imagine this is your data processing function
This method ensures that only one line is in memory at a time, which is significantly more memory-efficient than loading the entire file at once.
3. Chaining Generators for Complex Data Processing
Generators can be chained together to perform complex data processing tasks, piping the output of one generator to another. This pattern is akin to Unix command pipelines, where the output of one command is the input to the next.
Here's an example of chaining generators:
def filter_even_numbers(numbers):
    for number in numbers:
        if number % 2 == 0:
            yield number

numbers = (x for x in range(1, 1000000))  # a generator expression
filtered_numbers = filter_even_numbers(numbers)

for even in filtered_numbers:
    print(even)
In this scenario, a generator expression produces a stream of numbers, and the filter_even_numbers function processes them to yield only even numbers. This approach can be extended for more complex transformations.
4. Performance Considerations and Best Practices
While generators are incredibly memory-efficient, they should be used thoughtfully to maximize performance. Here are some best practices to consider when using generators:
- Avoid Generators for Small Datasets: For smaller datasets, the overhead of creating a generator may not be justified. Simple lists or other iterables might be more straightforward.
- Leverage Generator Comprehensions: Similar to list comprehensions, generator comprehensions are concise and memory-efficient, especially beneficial for filtering or transforming data.
- Be Mindful of State: Generators maintain state between consecutive executions of the
yieldstatement. This can be advantageous but also requires careful management to avoid unexpected behaviors.
5. Debugging and Testing Generators
Debugging generators can be slightly more challenging than regular functions due to their stateful nature. However, Python provides tools to make this easier. The inspect module, for example, allows you to introspect generator objects, providing insight into their current state and location.
Additionally, writing tests for generators is crucial to ensure they behave as expected. Using Python's built-in unittest or pytest frameworks can facilitate testing, checking both their output and the order of the elements produced.
Here's a simple test case using unittest:
import unittest

def generate_numbers(n):
    for i in range(n):
        yield i

class TestGenerators(unittest.TestCase):
    def test_generate_numbers(self):
        gen = generate_numbers(3)
        self.assertEqual(list(gen), [0, 1, 2])

if __name__ == '__main__':
    unittest.main()
By carefully implementing and testing your generators, you can ensure robust and efficient data processing workflows.
In conclusion, Python generators are a potent tool for any programmer dealing with large datasets. By providing on-demand data generation, they help optimize memory usage and performance, making them ideal for big data processing tasks. We hope this guide helps you effectively incorporate generators into your Python projects.
Useful links: