
Data Cleaning in Pandas: Handling Missing Values Like a Pro
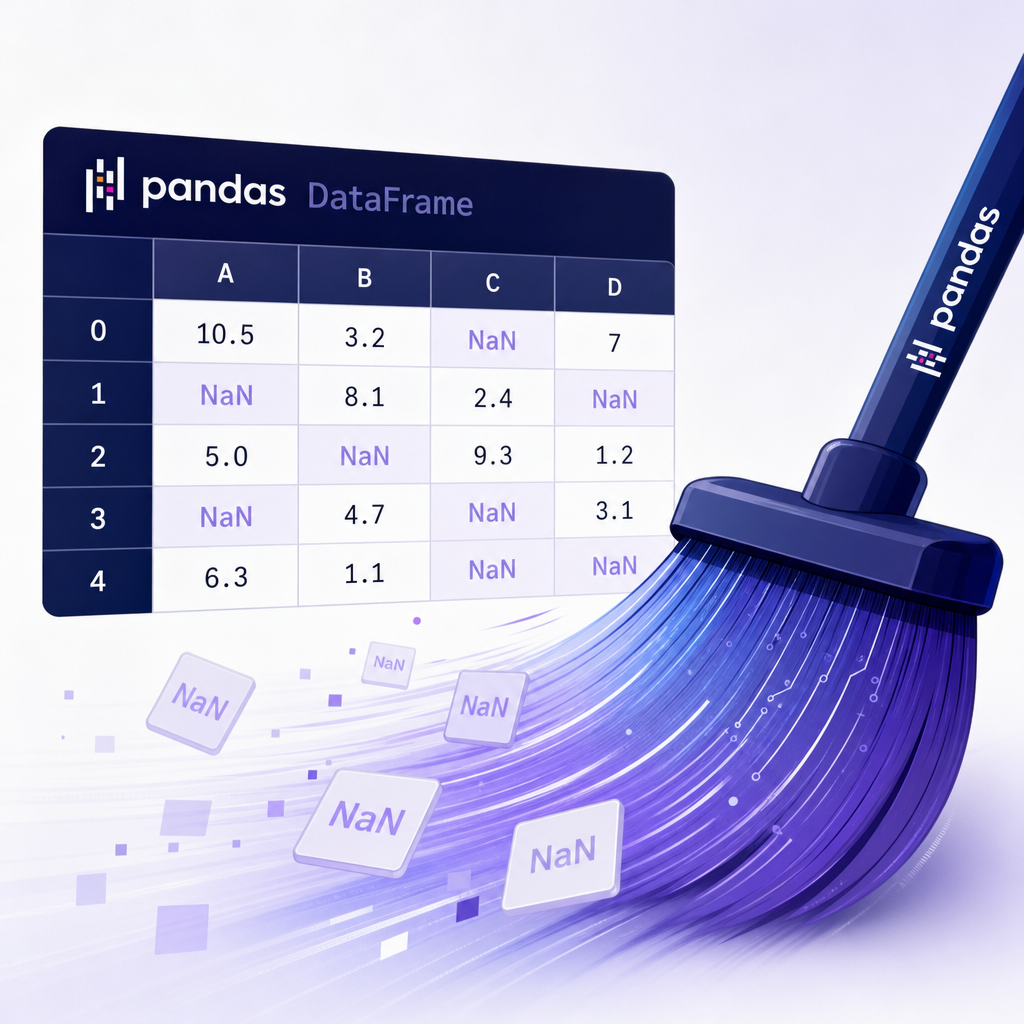
Data cleaning is one of the most critical tasks you’ll face as a data scientist or analyst. Preparing your dataset for analysis is often a make-or-break step, and Pandas—the versatile Python library—stands as a powerful ally in this endeavor. Handling missing values is a common challenge when working with real-world datasets, and doing it efficiently is key to deriving accurate insights. In this post, we will cover how you can handle missing values in Pandas effectively.
1. Identifying Missing Values
The first step to handling missing data is identifying where it occurs. Pandas provides several methods to accomplish this. The isna() and isnull() functions help identify missing entries within a DataFrame.
import pandas as pd

# Sample DataFrame
data = {'A': [1, 2, None], 'B': [5, None, 1], 'C': [None, 3, 3]}
df = pd.DataFrame(data)

# Identifying missing values
df.isna()
This simple code will return a DataFrame of boolean values indicating where NaNs exist. This is useful for getting an overview of which columns and rows are affected.
2. Counting Missing Values
Once you’ve identified missing values, the next logical step is to quantify them. This can help you decide your next steps based on the extent of the missing data.
# Count missing values per column
missing_count = df.isnull().sum()
print(missing_count)
This code outputs the number of missing values per column, a quick way to assess the situation.
3. Dropping Missing Values
One of the simplest ways to handle missing data is to drop the affected rows or columns altogether using the dropna() method. This is ideal when you’re dealing with minimal missing data compared to the size of your dataset.
# Drop rows with missing values
df_dropped_rows = df.dropna()
print(df_dropped_rows)  # Rows with any missing value are removed

# Drop columns with missing values
df_dropped_columns = df.dropna(axis=1)
print(df_dropped_columns)  # Columns with any missing value are removed
While this method is straightforward, use it with caution as it can result in a significant loss of data.
4. Imputation Techniques
If dropping data is not an option, imputing missing values is the next best solution. The goal of imputation is to “fill in” the missing data intelligently, using either the mean, median, or mode of the column, depending on the context.
# Imputing with mean
mean_imputed = df.fillna(df.mean())
print(mean_imputed)

# Imputing with median
median_imputed = df.fillna(df.median())
print(median_imputed)
Using statistical measures offers a better approximation and ensures that data distribution remains more balanced than simply removing entries.
5. Advanced Techniques with Interpolation
Beyond simple imputation, you can use interpolation methods to fill in missing gaps. For time series or otherwise ordered data, interpolation offers a smart approach to estimating missing values:
# Interpolation
interpolated_df = df.interpolate()
print(interpolated_df)
The interpolate() function fills missing data by estimating values based on the surrounding data points. This allows for a more realistic approximation of what might have been there.
Each method of handling missing data in Pandas can be used independently or together, depending on the dataset and the nature of the project. Mastering these techniques ensures that you maintain the integrity and usability of your dataset while avoiding the common pitfalls of data preprocessing.
So, the next time you encounter those pesky NaNs in your dataset, employ these methods to clean your data and proceed with confidence!
Useful links: