
Efficiently Handle Large Datasets in Memory-Constrained Environments Using Java Collections
Handling large datasets in memory-constrained environments is a challenging but common scenario in software engineering. Java, with its extensive Collection Framework, provides effective solutions for managing data efficiently. In this blog post, we will explore techniques to optimise Java collection manipulation to better handle large datasets in environments where memory is a constraint.
Understanding Java Collections and Memory Use
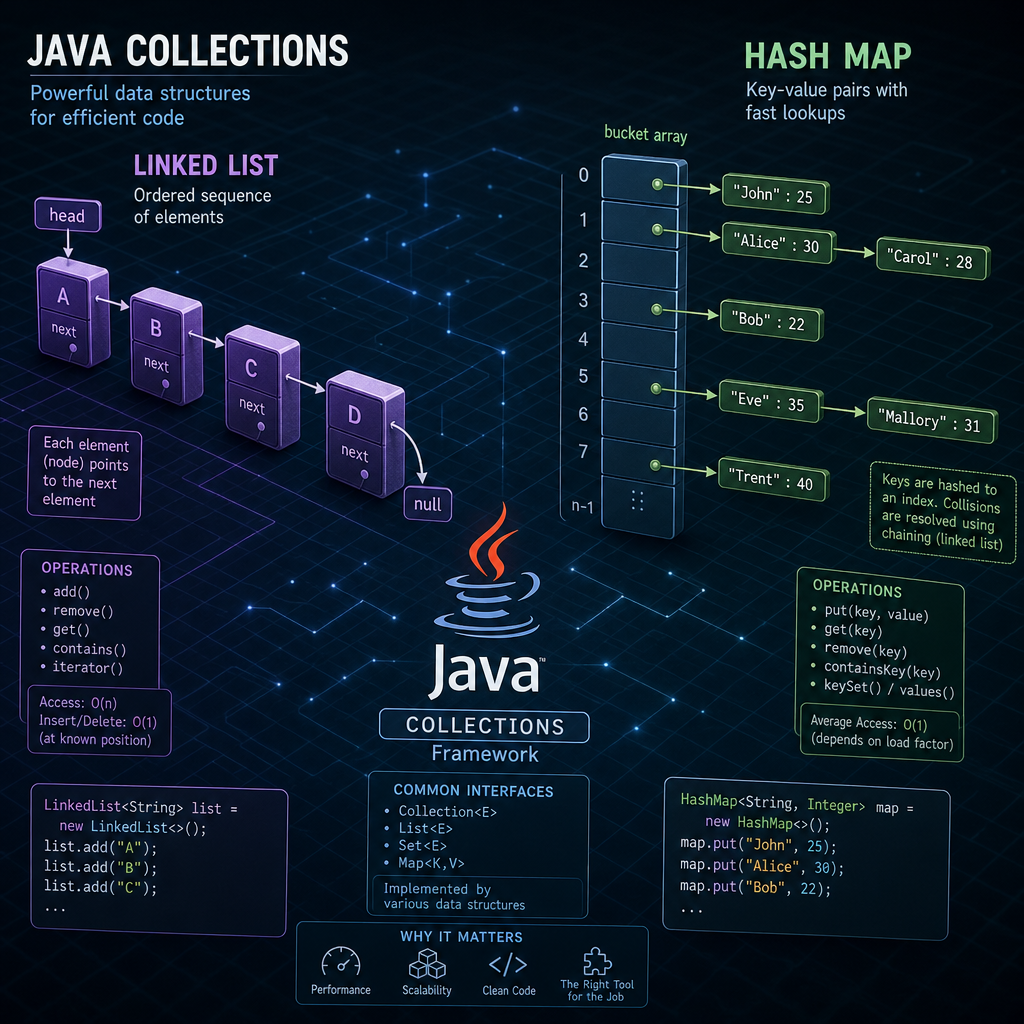
Java collections are data structures used to store and process groups of objects. The framework includes various types of collections such as lists, sets, and maps. Each collection type serves different use cases, and selecting the right one is crucial for optimizing memory usage.
For instance, an ArrayList provides resizable arrays, which can be beneficial when frequent random access is needed. However, it may lead to memory overhead due to resizing operations. The LinkedList, on the other hand, is more efficient in memory for insertions and deletions, but it can consume more space for storing node references.
List<String> arrayList = new ArrayList<>();
List<String> linkedList = new LinkedList<>();
Choosing between ArrayList and LinkedList can dramatically affect memory usage depending on the application’s needs.
Using Streams for Efficient Memory Handling
Java 8 introduced the Stream API as a powerful tool for functional-style operations on collections. Streams process large datasets efficiently by using lazy evaluation, which significantly reduces memory overhead.
Consider processing a dataset to filter out specific elements. Instead of loading the entire dataset into memory using a loop, a stream allows data to be processed incrementally.
List<String> data = getData(); // Assume this retrieves a large dataset
List<String> filteredData = data.stream()
    .filter(item -> item.startsWith("A"))
    .collect(Collectors.toList());
The stream processes each element lazily, reducing the overall memory footprint.
Using Primitive Collections for Memory Optimization
Regular Java collections like ArrayLists operate on object wrappers instead of primitive data types, which introduces additional memory overhead. Libraries such as fastutil and Trove provide collections that directly store primitives, reducing memory usage significantly.
TIntArrayList primitiveList = new TIntArrayList();
primitiveList.add(1);
primitiveList.add(2);
primitiveList.add(3);
By using primitive collections, you can achieve significant memory savings, especially when dealing with large datasets of primitive values.
Memory-Sensitive Data Structures
Some specialized data structures are designed for memory efficiency, like HashSet and HashMap, by minimizing storage for similar elements. However, maintaining their performance involves optimizing initial capacity and load factor settings.
When using a HashMap to store a large dataset, you can initialize it to avoid excessive resizing:
Map<String, Integer> map = new HashMap<>(initialCapacity, loadFactor);Setting a higher initial capacity reduces the need for resizing but consumes more memory upfront.
Handling Datasets with External Memory Solutions
For extreme memory constraints, consider using external memory solutions such as database systems or file-based caching libraries. Libraries like Ehcache and Infinispan can alleviate memory stress by caching data outside of JVM memory space.
For example, integrating Ehcache into your application provides a transparent caching mechanism to improve memory efficiency:
CacheManager cacheManager = CacheManagerBuilder.newCacheManagerBuilder()
    .withCache("preConfigured",
        CacheConfigurationBuilder.newCacheConfigurationBuilder(Long.class, String.class,
            ResourcePoolsBuilder.heap(100)))
    .build();
cacheManager.init();
With this setup, only frequently accessed data remains in memory, minimizing overall memory usage.
Efficient memory management with Java collections is a critical skill when working with large datasets. By utilizing the right collection, optimizing stream operations, leveraging primitive collections, tweaking data structure configurations, and considering external solutions, developers can achieve high performance even under memory constraints.
Useful links: