
Effortless Data Cleaning in Pandas: Automating Routine Tasks
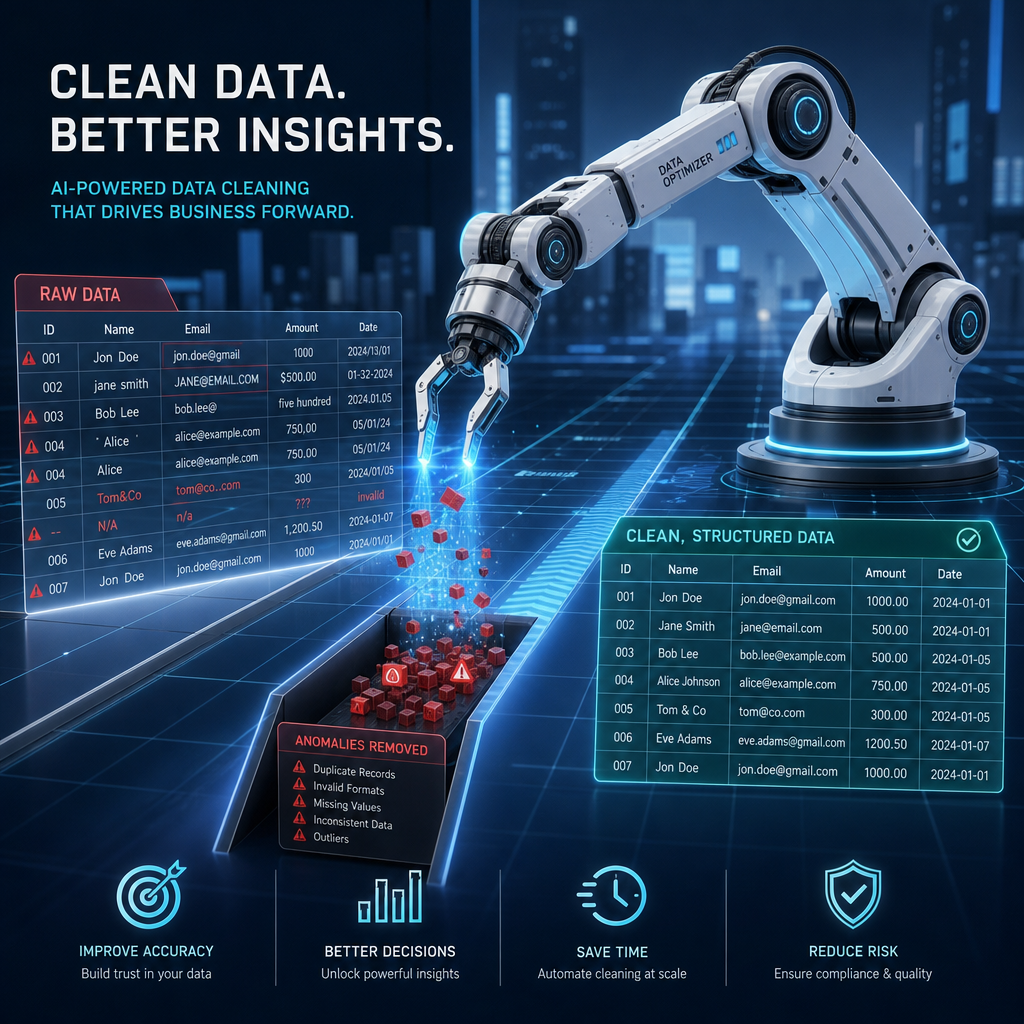
Pandas is an indispensable library in any data analyst’s toolkit, providing the tools necessary to perform efficient data preprocessing. Data cleaning can often become a tedious process, especially when dealing with large datasets. This article will guide you through automating some of the most common data cleaning tasks using Pandas, enabling you to streamline your data preprocessing pipelines effectively.
1. Handling Missing Values
One of the most frequently encountered issues in datasets is missing values. Pandas offers various methods to detect and handle these missing data effectively.
The isnull() function can identify missing values in your dataset. Once detected, missing values can be addressed using fillna(), dropna(), or other methods based on your analysis requirements.
import pandas as pd

data = {'Name': ['Alice', 'Bob', None, 'Dave'],
        'Age': [24, None, 35, 29],
        'City': ['New York', 'Los Angeles', None, 'Chicago']}
df = pd.DataFrame(data)
# Identifying missing values
df.isnull()
# Filling missing values
df['Age'].fillna(df['Age'].mean(), inplace=True)
# Alternatively, dropping missing values
df.dropna(inplace=True)
By utilizing these methods, you can ensure your dataset does not suffer from issues due to missing information, thereby improving the reliability of your analyses.
2. Removing Outliers
Outliers can skew your data analysis. Therefore, it’s critical to address them appropriately. A common method of identifying outliers is using the interquartile range (IQR).
Q1 = df['Age'].quantile(0.25)
Q3 = df['Age'].quantile(0.75)
IQR = Q3 - Q1
# Defining lower and upper bounds
lower_bound = Q1 - 1.5 * IQR
upper_bound = Q3 + 1.5 * IQR
# Removing outliers
df_filtered = df[(df['Age'] >= lower_bound) & (df['Age'] <= upper_bound)]
This code will remove any records with 'Age' values outside the defined bounds, ensuring a cleaner dataset for analysis.
3. Standardizing Data Formats
Consistency in data formats is crucial for accurate analysis. For example, ensuring all date formats are consistent within a dataset is necessary when working with time-series data.
df['Date'] = pd.to_datetime(df['Date'], errors='coerce')
Setting the errors='coerce' parameter helps convert any invalid strings to NaT (NaT stands for Not-a-Time), which can then be handled using our missing data strategy.
4. Automating Redundant Tasks
You can automate repetitive cleaning tasks using functions and the Pandas apply method. Writing custom functions allows for reuse and consistency across multiple datasets.
def clean_data(df):
    df.fillna(df.mean(), inplace=True)
    df['Date'] = pd.to_datetime(df['Date'], errors='coerce')
    # More cleaning steps
    return df

df = clean_data(df)
By defining such functions, you ensure that the same cleaning procedures are applied consistently, thus reducing errors and saving time.
5. Leveraging Pandas Profiling for Insights
Pandas Profiling can generate a comprehensive data report, providing insights and potential issues in your data.
from pandas_profiling import ProfileReport

profile = ProfileReport(df, title="Pandas Profiling Report")
profile.to_notebook_iframe()
This tool can automatically suggest data cleaning strategies, thus aiding in efficient preprocessing pipeline creation.
Conclusion
Cleaning data is a vital step in the data preprocessing pipeline. By leveraging Pandas' powerful functions, it becomes possible to automate repetitive tasks, maintain consistency, and improve the reliability of the results. Efficient data cleaning not only saves time but also aids in deriving meaningful insights from the data.
Useful links: